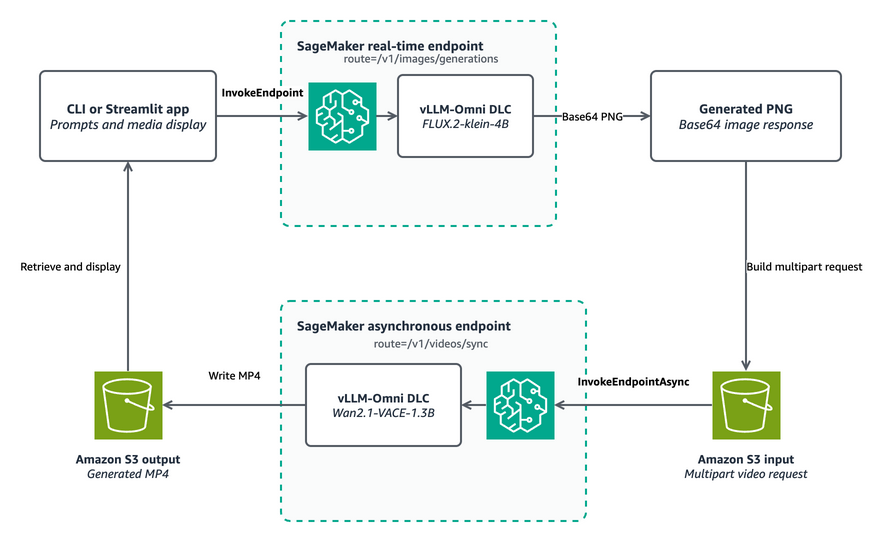
Deploy two generative media models from one AWS vLLM-Omni Deep Learning Container on Amazon SageMaker AI. Generate an image with FLUX.2-klein through real-time inference, then animate it into video with Wan2.1-VACE through asynchronous inference, and retrieve the MP4 from Amazon S3.
Generate images and video with vLLM-Omni on SageMaker AI – Part 2
Résumé de la publication. Les conditions de AWS Machine Learning ne permettent pas de reproduire l'article en intégralité : retrouvez le texte complet sur le site d'origine.
Résumé de la source (Anglais)
Lire l'article complet
aws.amazon.com