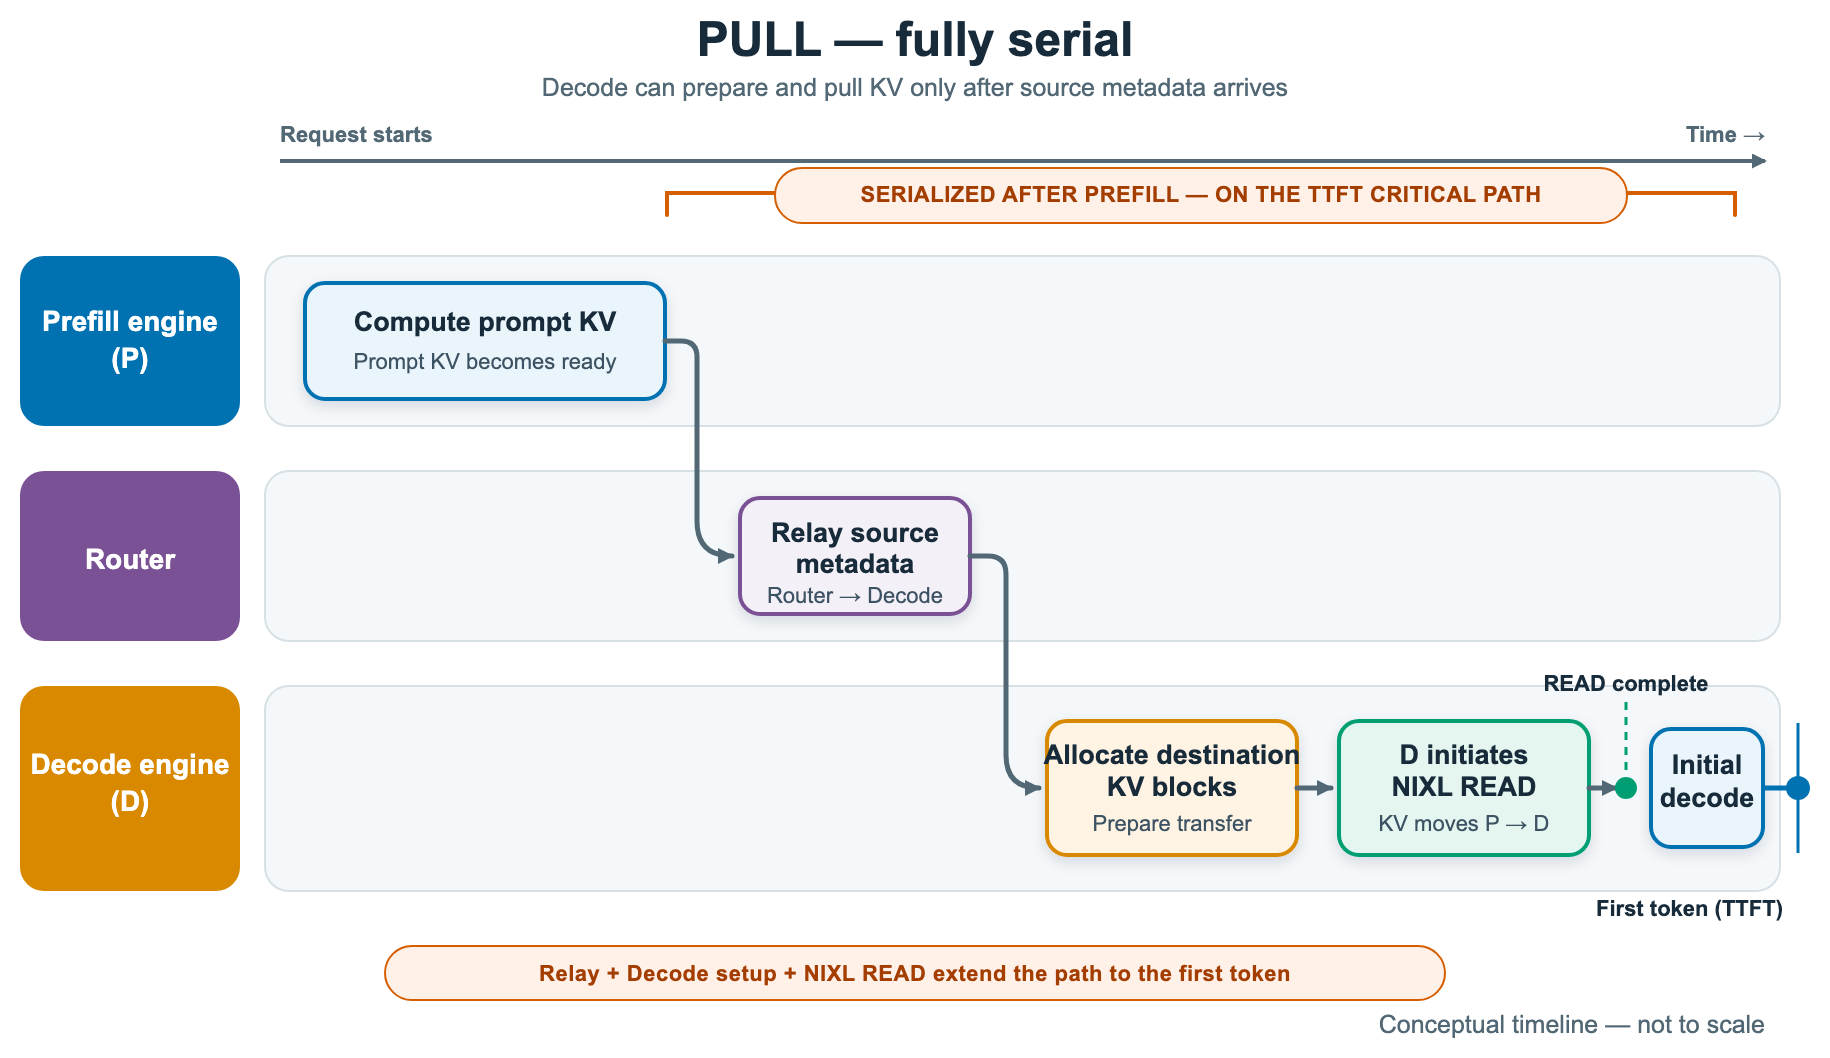
vLLM's prefill-decode disaggregation splits LLM inference across engine instances but must transfer the KV cache between them. This post introduces a push-based NIXL connector that moves transfer coordination off the critical path, delivering up to 3x better TTFT and 30% better TPOT in benchmarks on Amazon EC2 P5en instances with AWS EFA.
Push-based KV transfer to improve TTFT and TPOT for disaggregated inference in vLLM
Résumé de la publication. Les conditions de AWS Machine Learning ne permettent pas de reproduire l'article en intégralité : retrouvez le texte complet sur le site d'origine.
Résumé de la source (Anglais)
Lire l'article complet
aws.amazon.com