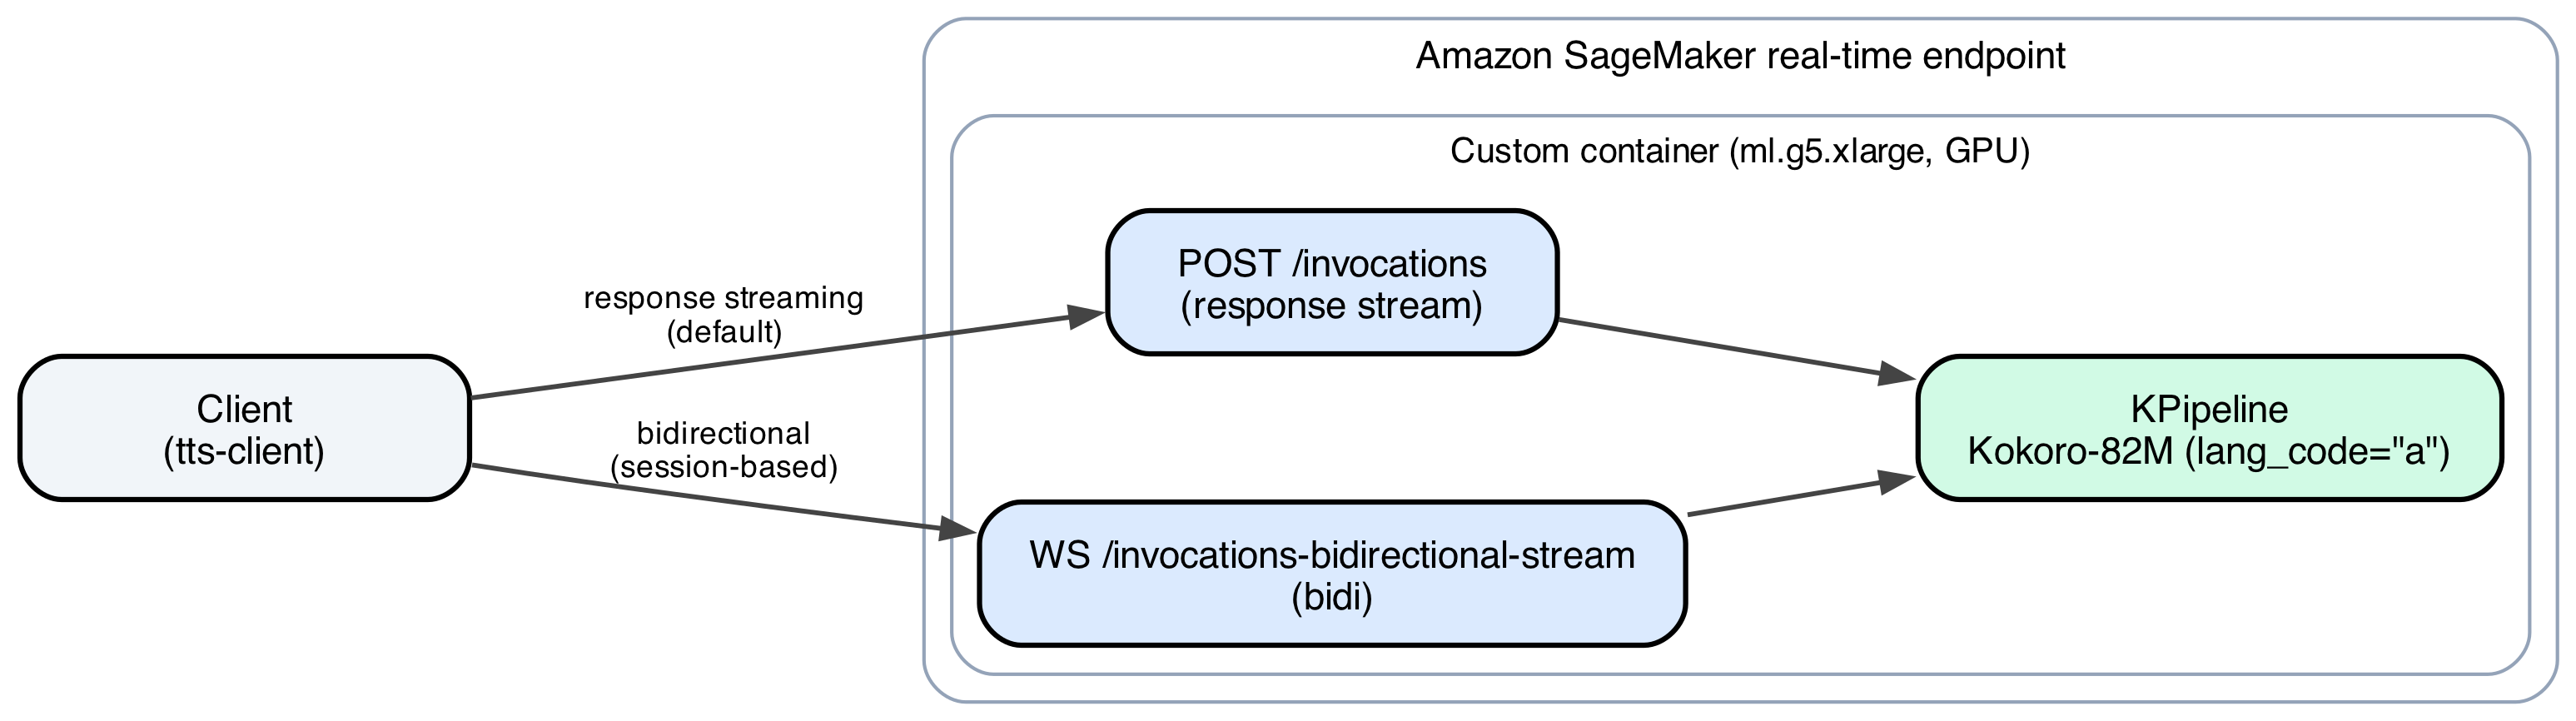
Teams deploying custom text-to-speech models on Amazon SageMaker AI often guess at autoscaling thresholds, and a wrong guess either wastes GPU spend or breaches a latency SLO. This post deploys Kokoro-82M as a custom container and derives a measured autoscaling policy from two live-endpoint measurements, Q_max and T_total, instead of guesswork.
Stop guessing auto scaling targets for TTS on Amazon SageMaker AI
Résumé de la publication. Les conditions de AWS Machine Learning ne permettent pas de reproduire l'article en intégralité : retrouvez le texte complet sur le site d'origine.
Résumé de la source (Anglais)
Lire l'article complet
aws.amazon.com