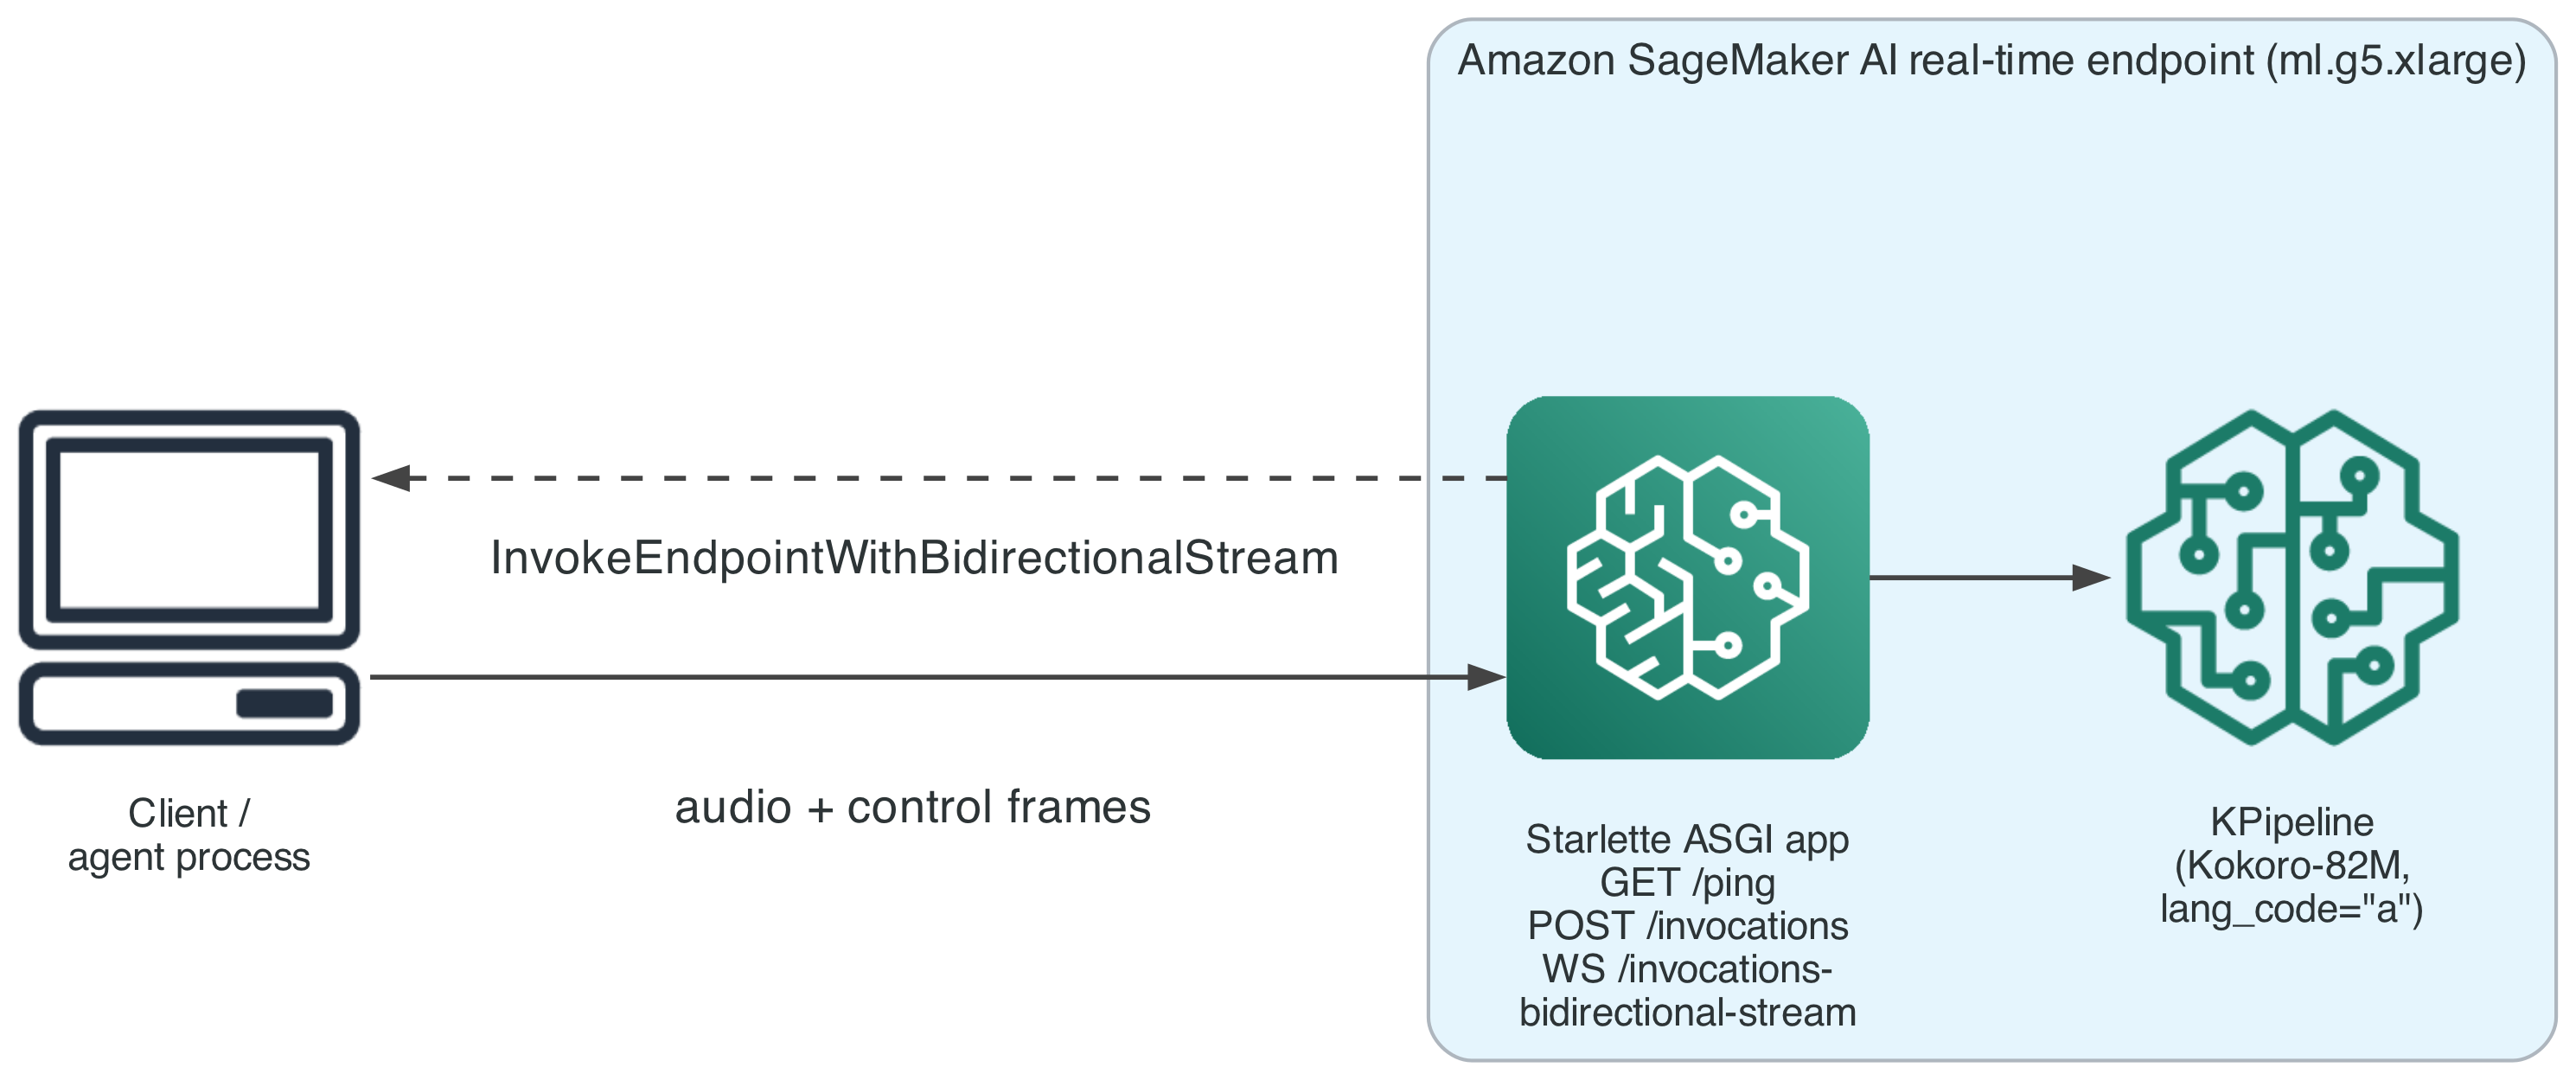
Voice agents often wait for an agent's full response before starting speech synthesis, adding latency users feel directly. This post shows how to stream each sentence to a Kokoro-82M text-to-speech model on Amazon SageMaker AI as the agent produces it, and how to get that audio back to a browser over Server-Sent Events or a unified binary transport.
Stream low-latency speech from AI agents using Kokoro TTS on Amazon SageMaker AI
Riassunto della pubblicazione. Le condizioni di AWS Machine Learning non consentono la riproduzione integrale dell'articolo: leggi il testo completo sul sito originale.
Riassunto della fonte (Inglese)
Leggi l'articolo completo
aws.amazon.com