Ema raises $77M as AI starts eating into enterprise software and services
Ema has raised $140 million to date and has more than 50 enterprise customers, including Google and Microsoft.
LLM, modelli di base, finestre di contesto e addestramento.
Argomento · 428 articoli
Ema has raised $140 million to date and has more than 50 enterprise customers, including Google and Microsoft.
Using GPT-5.6, Ringg powers multilingual agents across voice, chat, WhatsApp, and web for 90% less cost vs. GPT-4.1.
With GPT‑6 Astra, invideo plans edits with greater precision, improves color correction and grading threefold, and produces 50 custom effects in one day.
GPT-6 Astra produces more structured, context-aware legal documents, freeing lawyers to focus on strategy.
Learn how Airbnb is expanding access to GPT-6 Astra and OpenAI frontier models to help engineering teams solve bugs, design systems, and ship faster.
We’re introducing a new life sciences research group and laboratory at Anthropic. Our focus is on fundamental biology research using Claude: exploring datasets of DNA to identify uncharacterized protein families, generating hypotheses at scale, and testing…
Learn how GPT-6 improves prompt caching with higher cache hit rates, new diagnostics, explicit breakpoints, and controls that reduce latency and costs.
GPT-6 Sol and GPT-6 Luna are now generally available on Amazon Bedrock, giving you more options to match intelligence and efficiency to each workload.
OpenAI is launching two new models, which it says are cut from the same cloth as Astra.
Meet GPT-6 Sol and Luna, two models that bring frontier intelligence to everyday work with different balances of capability and cost.
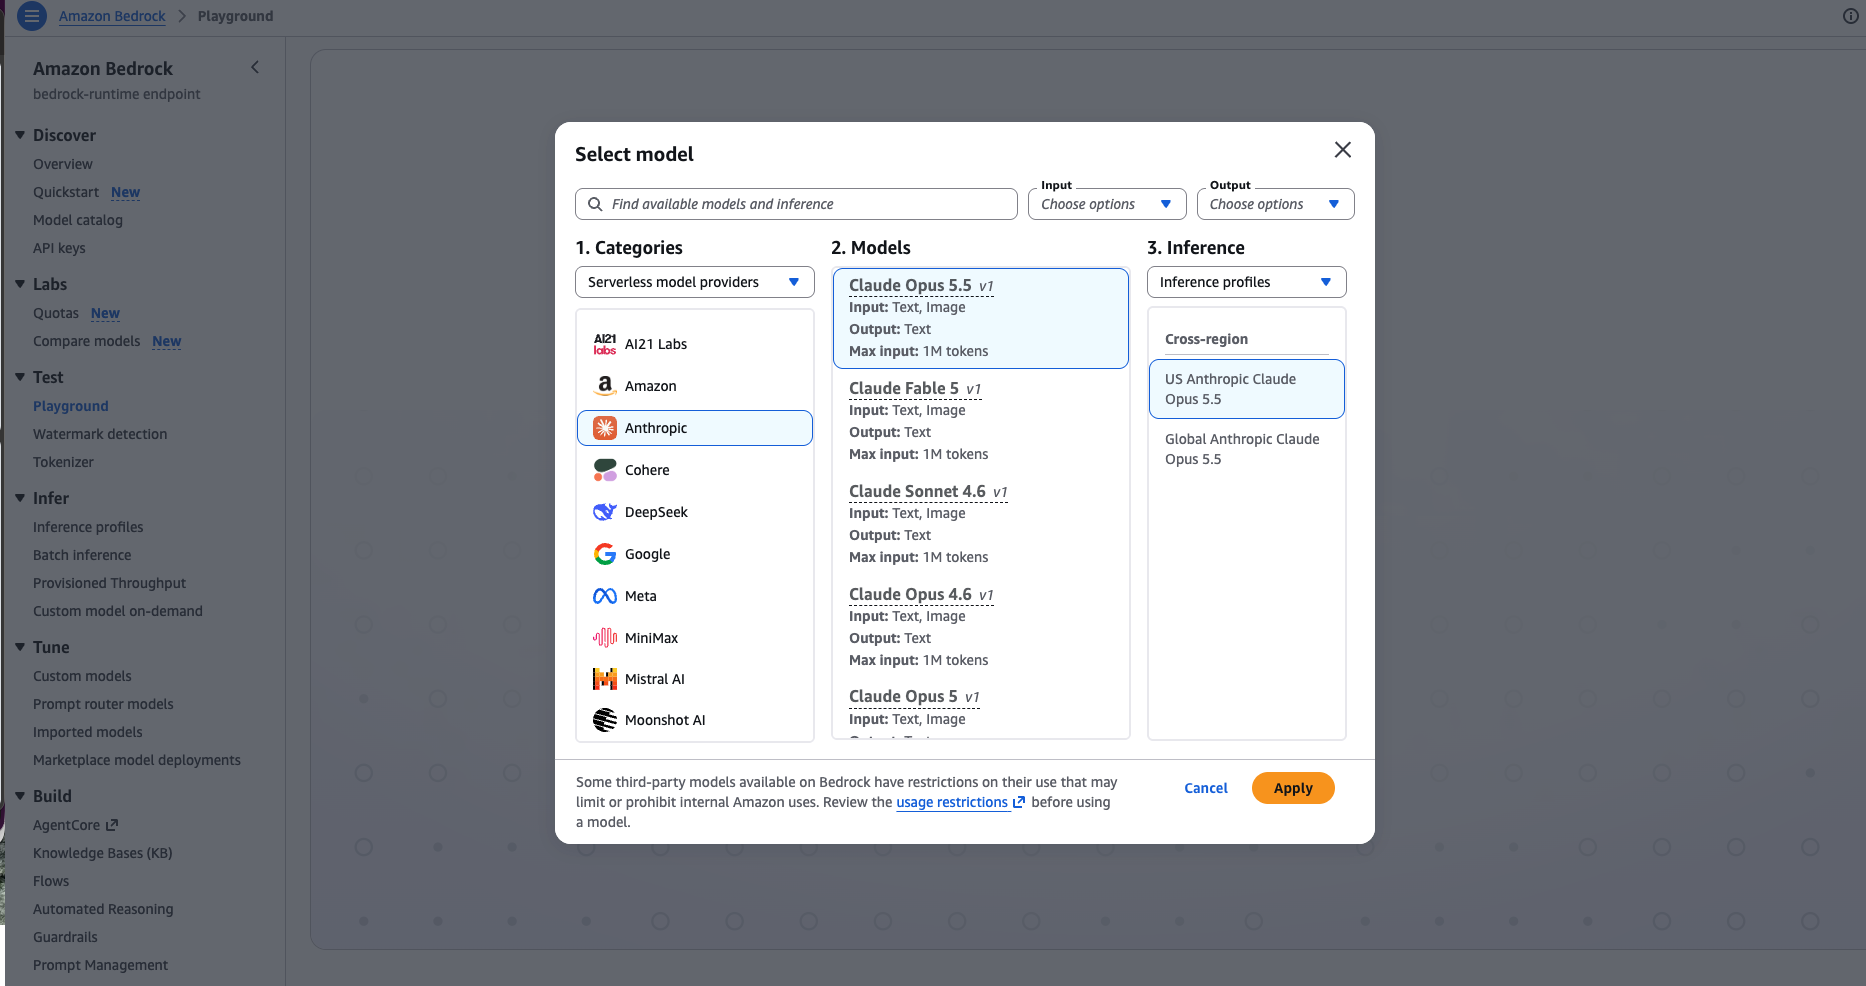
Claude Opus 5.5, Anthropic's most capable Opus model for agentic coding, knowledge work, and long-running tasks, is now available on Amazon Bedrock and Claude Platform on AWS. This post covers what's new in Opus 5.5, practical guidance, and how to start…
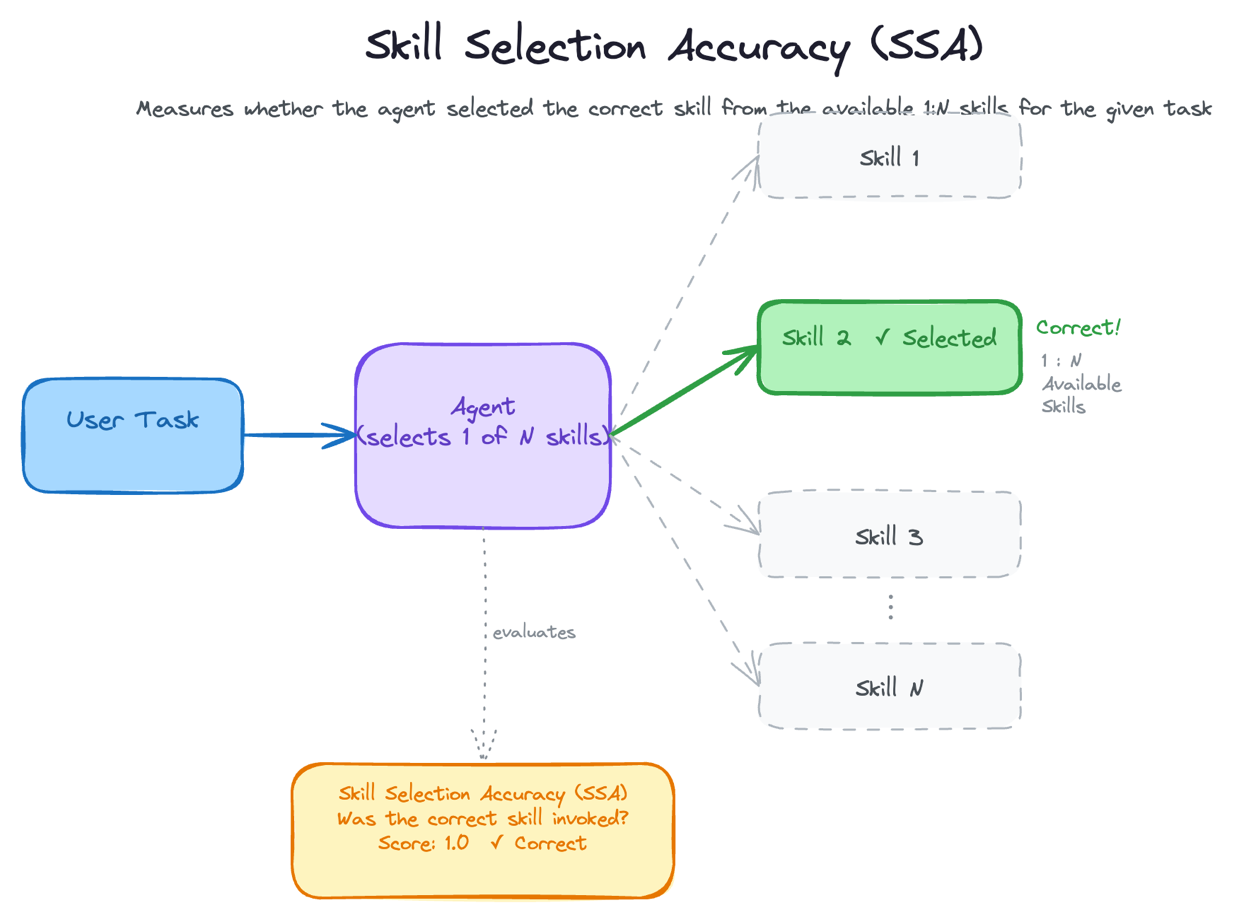
Skills let you encode domain-specific procedures as reusable, portable instructions for agents, but a fluent answer doesn't prove the agent picked the right skill or followed it. Learn how to measure skill selection and instruction following with Strands…