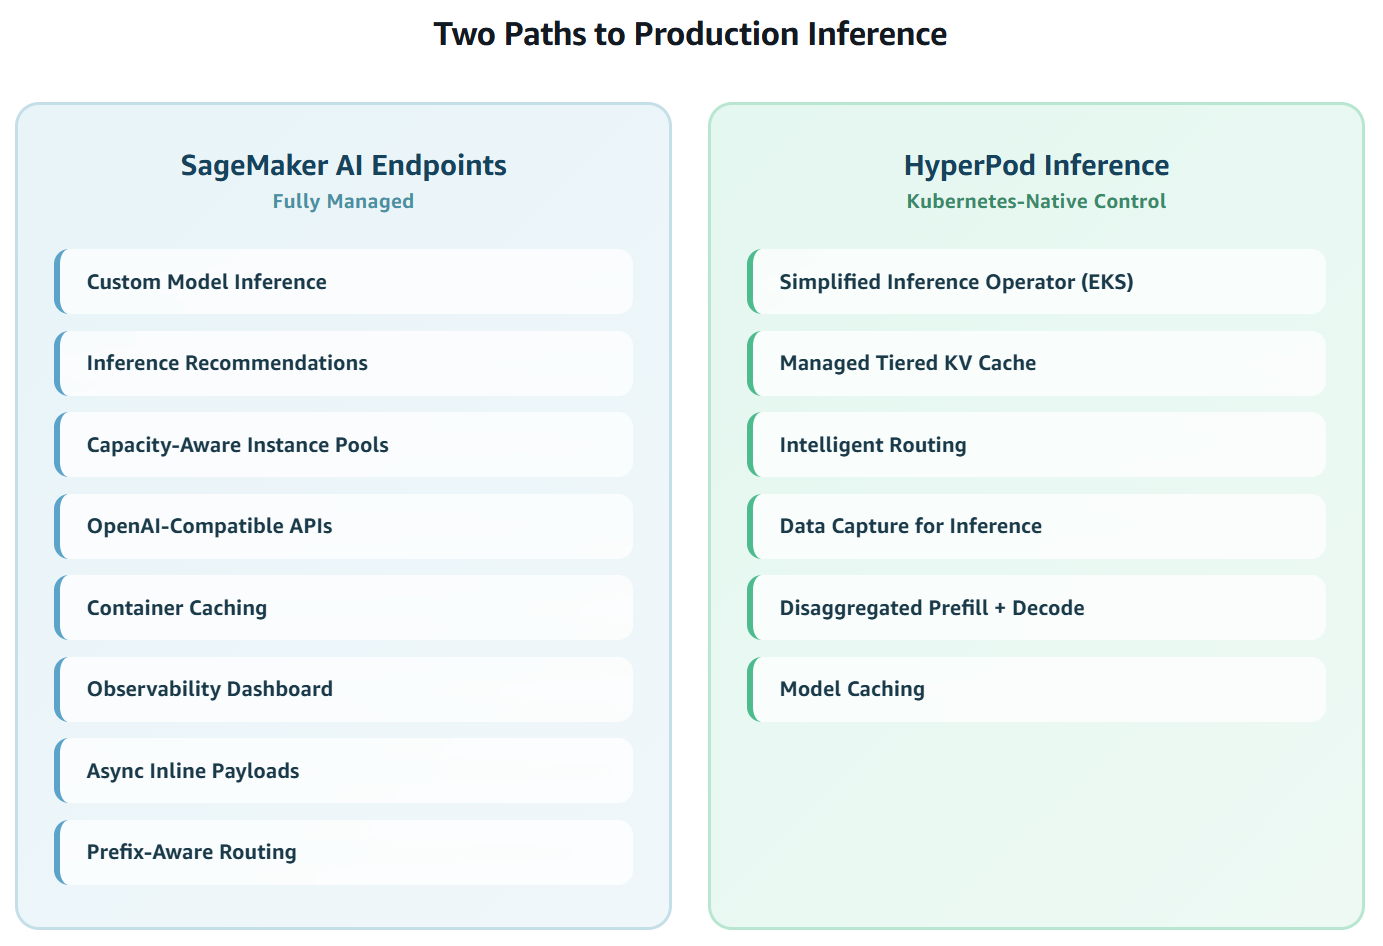
Amazon SageMaker AI shipped 13 inference launches in year-to-date across two deployment paths: fully managed endpoints and Amazon SageMaker HyperPod Inference. This post reviews each launch, from inference recommendations and capacity-aware instance pools to tiered KV caching and disaggregated prefill and decode.
Amazon SageMaker Inference: 2026 year-to-date launches in review
Publication summary. The terms of AWS Machine Learning do not allow reproduction of the full article: read the complete text on the original website.
Source summary (English)
Read the full article
aws.amazon.com