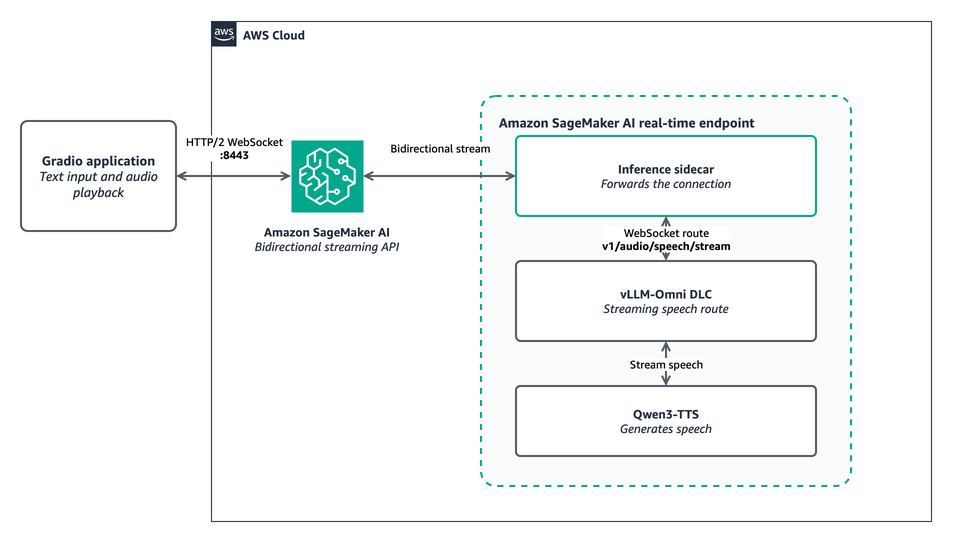
Deploy a text-to-speech model on Amazon SageMaker AI with the AWS vLLM-Omni Deep Learning Container and stream generated speech over a persistent bidirectional connection. This Part 1 tutorial deploys Qwen3-TTS and streams speech through a Gradio application.
Build real-time voice applications with vLLM-Omni on SageMaker AI – Part 1
Publication summary. The terms of AWS Machine Learning do not allow reproduction of the full article: read the complete text on the original website.
Source summary (English)
Read the full article
aws.amazon.com