Integrate NVIDIA Resiliency Extension (NVRx) into PyTorch FSDP training on Amazon EKS to overlap checkpoint I/O with training and recover from GPU faults in seconds. This post covers async checkpointing, in-process restart, and ft_launcher in-job restart, with H100 benchmarks at 2 to 8 nodes showing 99%+ training efficiency and second-scale recovery.
Fault tolerant distributed training on Amazon EKS using NVRx
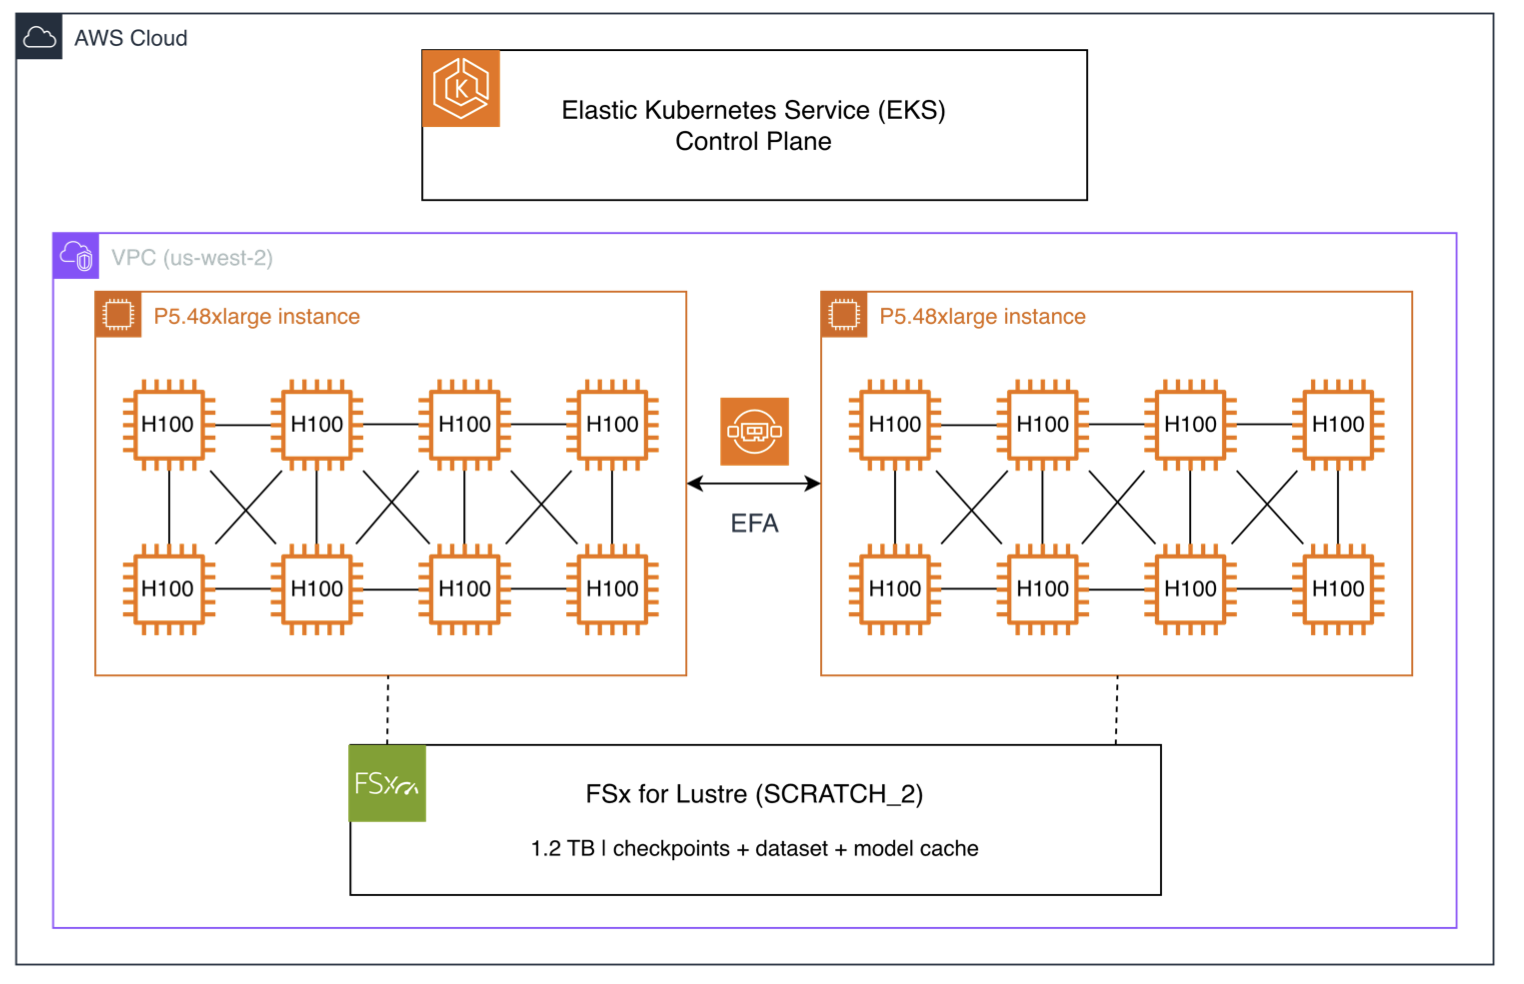
Publication summary. The terms of AWS Machine Learning do not allow reproduction of the full article: read the complete text on the original website.
Source summary (English)
Read the full article
aws.amazon.com