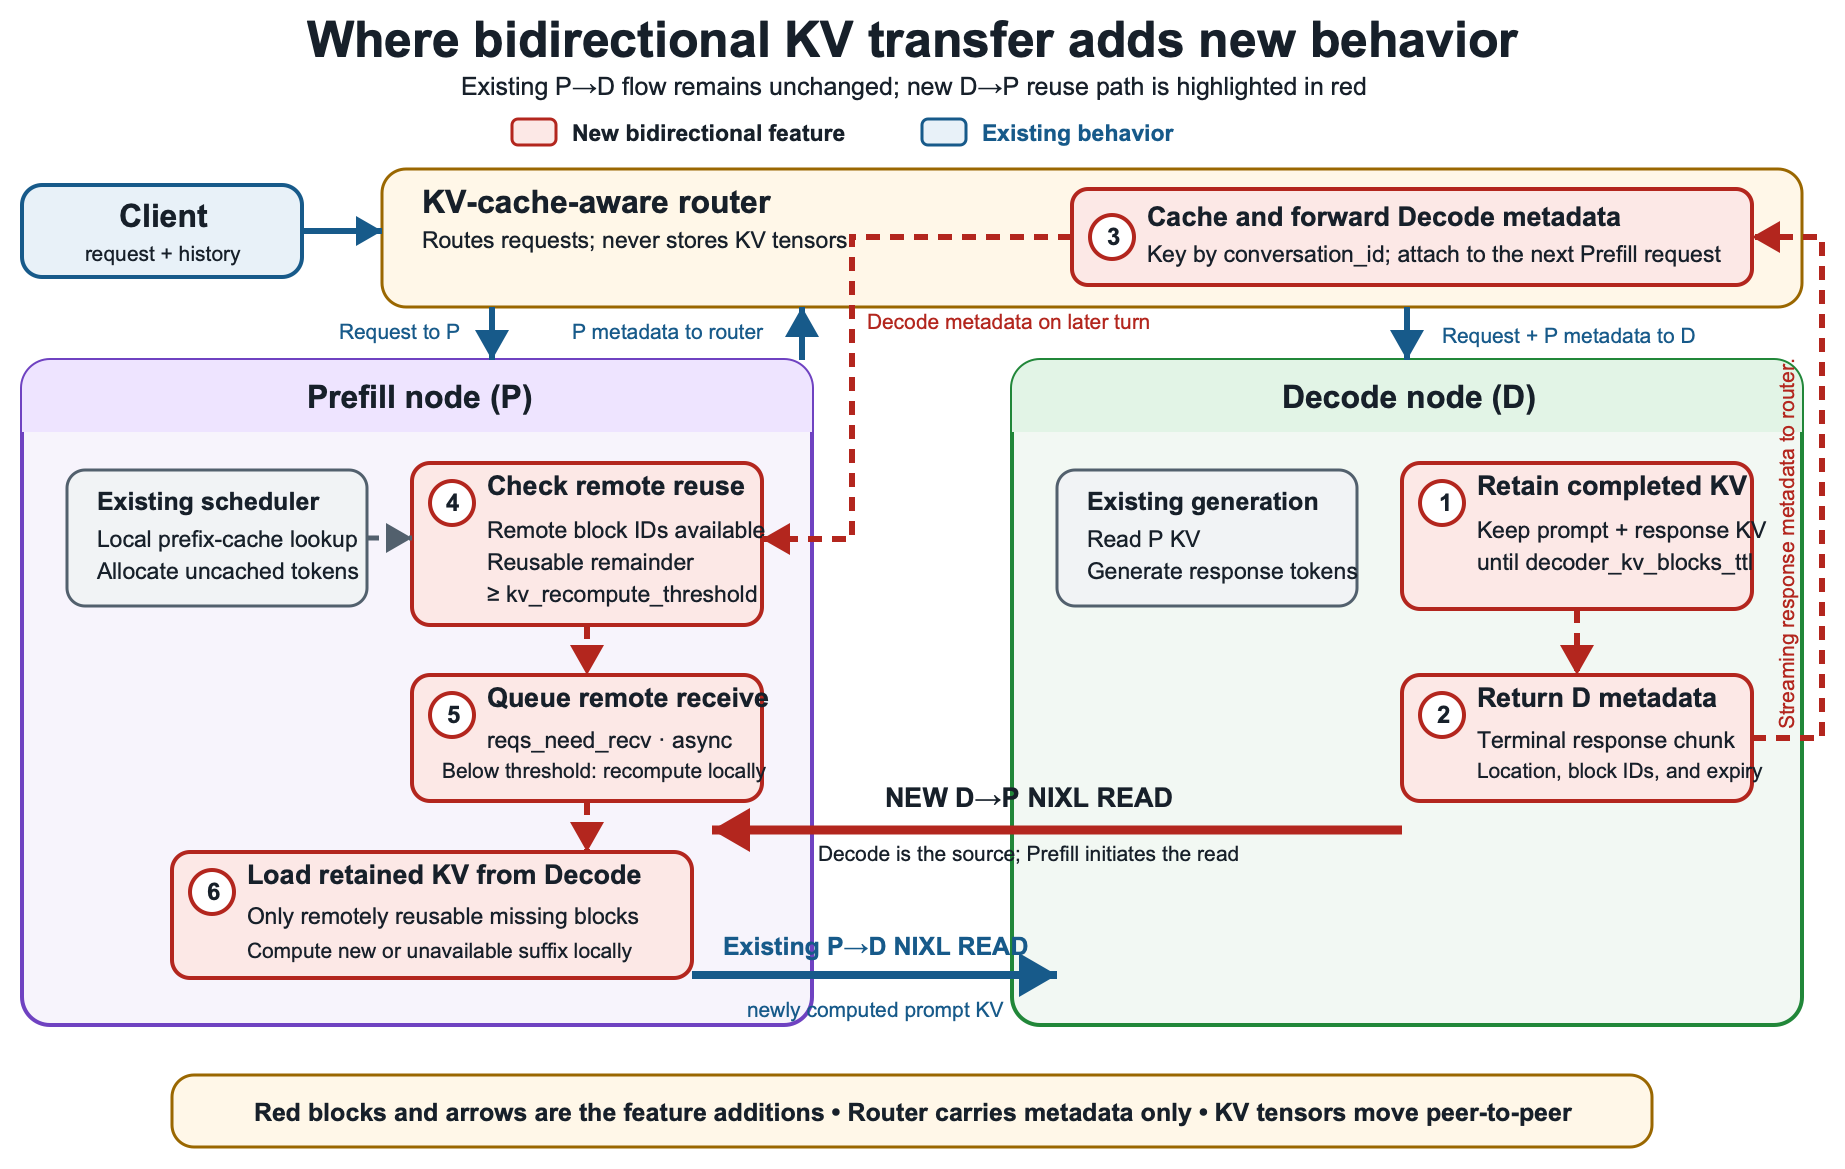
Multi-turn agentic workloads reprocess growing conversation context each turn, driving up latency. See how bi-directional KV cache transfer lets prefill and decode nodes reuse previously computed context across turns, cutting time to first token by up to 1.6x for Qwen3-32B and 3.3x for GLM-5-FP8 on Amazon EC2 P5en instances with EFA.
Improve TTFT for multi-turn agentic workloads with bi-directional KV transfer in vLLM
Publication summary. The terms of AWS Machine Learning do not allow reproduction of the full article: read the complete text on the original website.
Source summary (English)
Read the full article
aws.amazon.com