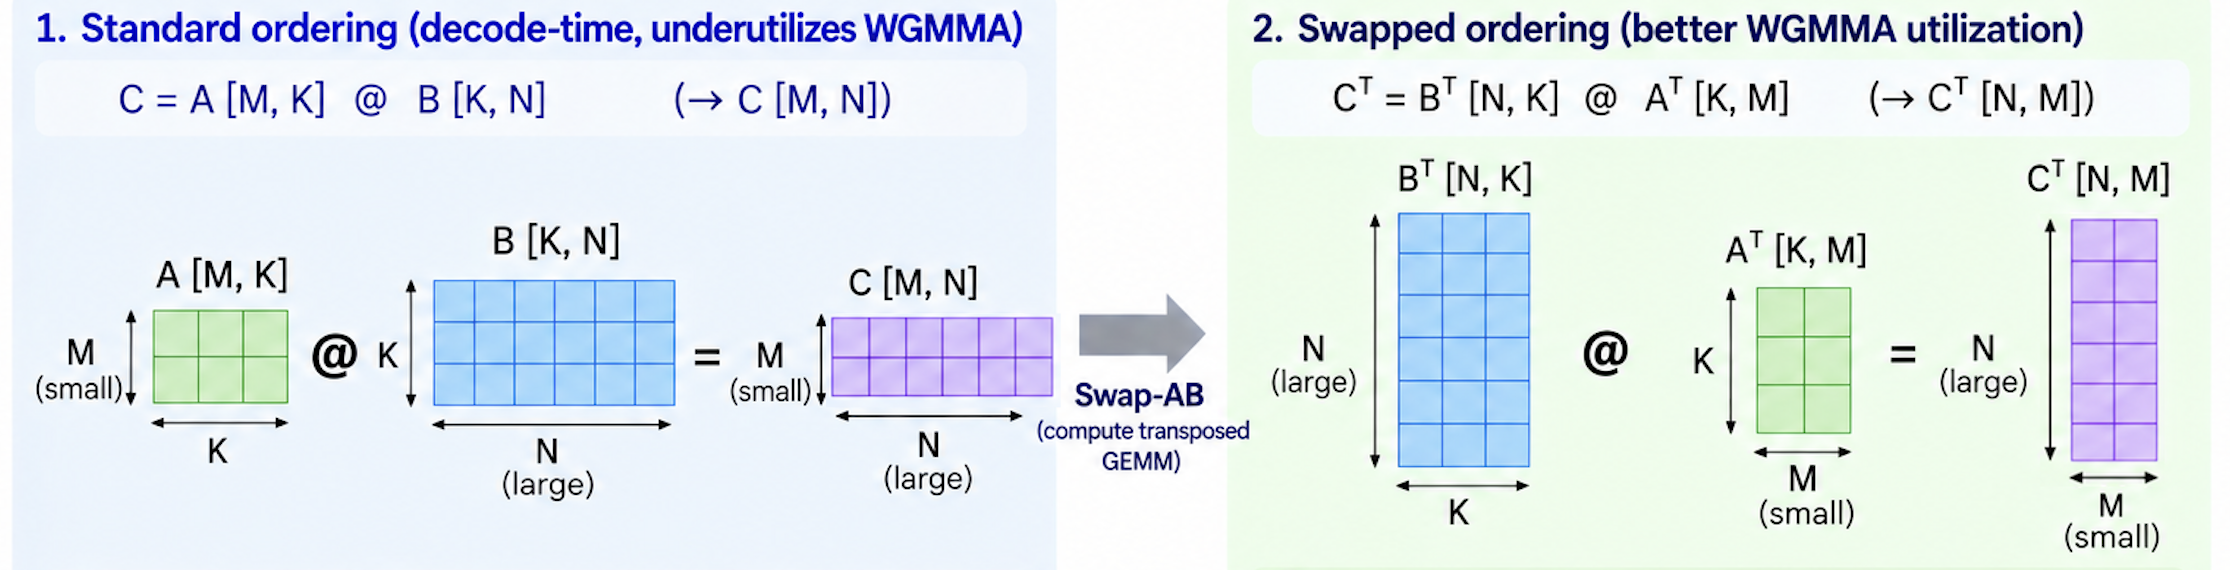
AWS engineers share kernel optimizations for fused Mixture-of-Experts (MoE) models on Amazon SageMaker AI: Swap-AB for WGMMA utilization, Triton backend routing for FP8 quantization, and eliminating Triton JIT recompilation. Together they deliver up to 10% higher throughput and up to 9% faster Time to First Token on H200 GPUs.
Mixture-of-Experts kernel engineering on Amazon SageMaker AI
Résumé de la publication. Les conditions de AWS Machine Learning ne permettent pas de reproduire l'article en intégralité : retrouvez le texte complet sur le site d'origine.
Résumé de la source (Anglais)
Lire l'article complet
aws.amazon.com