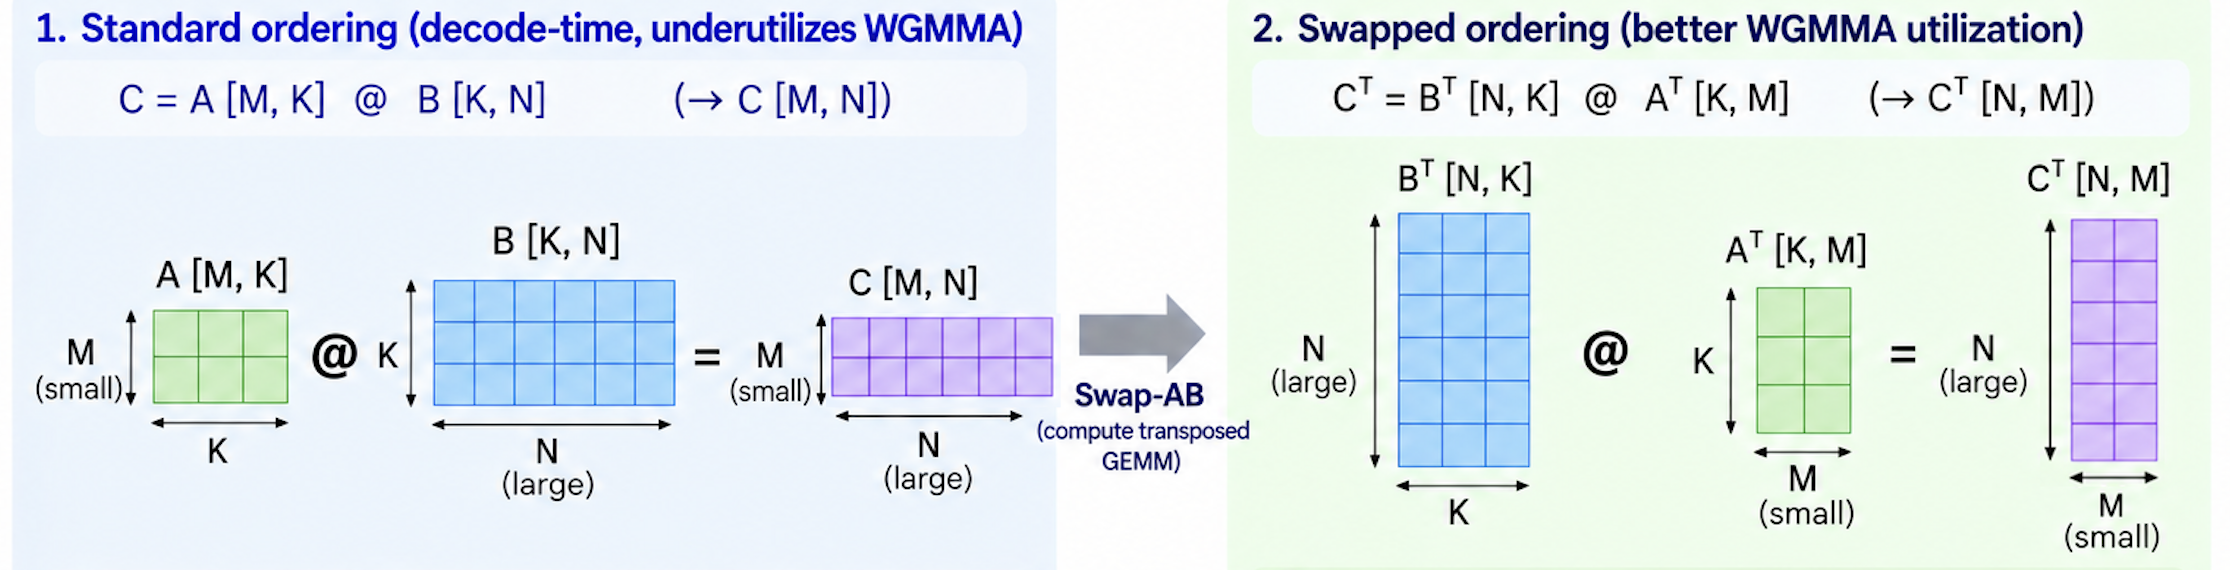
AWS engineers share kernel optimizations for fused Mixture-of-Experts (MoE) models on Amazon SageMaker AI: Swap-AB for WGMMA utilization, Triton backend routing for FP8 quantization, and eliminating Triton JIT recompilation. Together they deliver up to 10% higher throughput and up to 9% faster Time to First Token on H200 GPUs.
Mixture-of-Experts kernel engineering on Amazon SageMaker AI
Riassunto della pubblicazione. Le condizioni di AWS Machine Learning non consentono la riproduzione integrale dell'articolo: leggi il testo completo sul sito originale.
Riassunto della fonte (Inglese)
Leggi l'articolo completo
aws.amazon.com