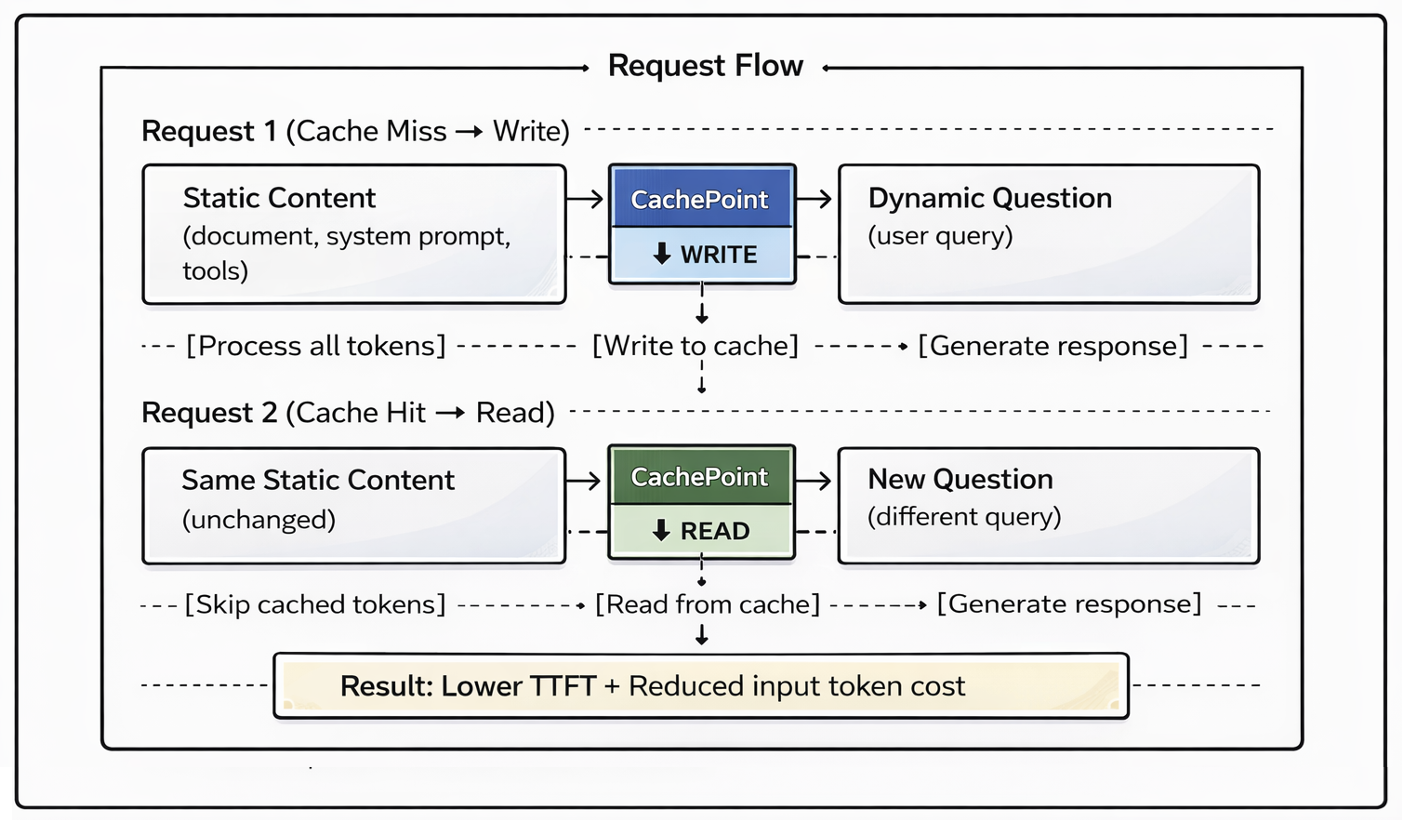
Prompt caching in Amazon Bedrock can cut input token costs by up to 90% when you repeatedly send the same context to foundation models. This post walks through six practical prompt caching scenarios using the Converse API: message content, system prompt, tool definition, mixed TTL, tenant isolation, and LangChain integration.
Optimizing cost and latency with Amazon Bedrock prompt caching
Résumé de la publication. Les conditions de AWS Machine Learning ne permettent pas de reproduire l'article en intégralité : retrouvez le texte complet sur le site d'origine.
Résumé de la source (Anglais)
Lire l'article complet
aws.amazon.com