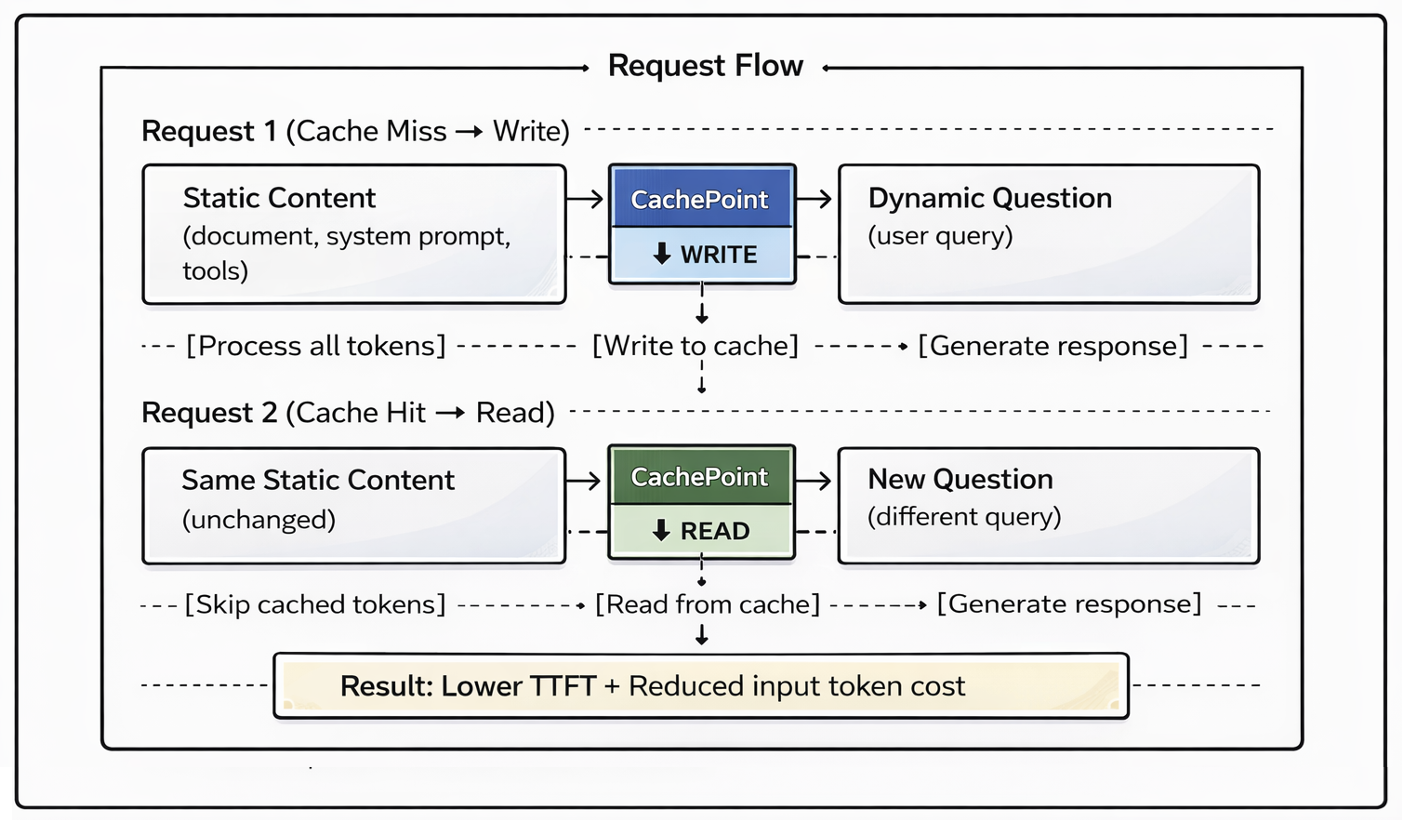
Prompt caching in Amazon Bedrock can cut input token costs by up to 90% when you repeatedly send the same context to foundation models. This post walks through six practical prompt caching scenarios using the Converse API: message content, system prompt, tool definition, mixed TTL, tenant isolation, and LangChain integration.
Optimizing cost and latency with Amazon Bedrock prompt caching
Riassunto della pubblicazione. Le condizioni di AWS Machine Learning non consentono la riproduzione integrale dell'articolo: leggi il testo completo sul sito originale.
Riassunto della fonte (Inglese)
Leggi l'articolo completo
aws.amazon.com