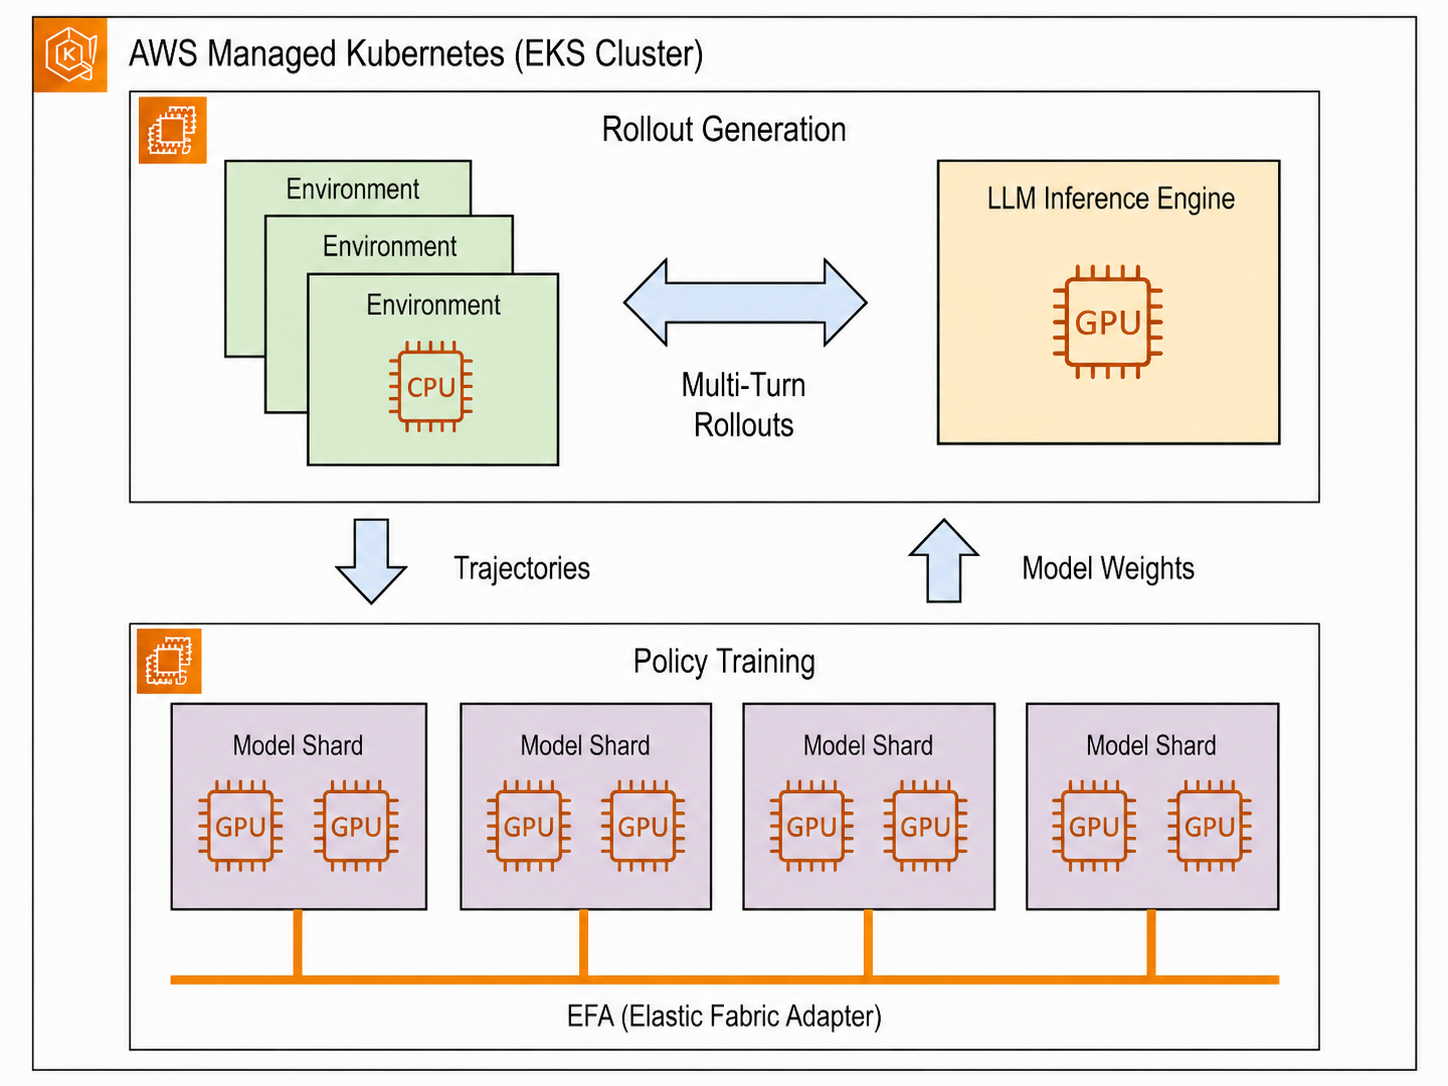
Learn how to scale Mixture-of-Experts (MoE) reinforcement learning on Amazon EKS using Elastic Fabric Adapter (EFA) and DeepEP. This post presents an architecture that combines Amazon EKS, EFA, and Amazon S3 and increased aggregate reinforcement learning rollout throughput by 40% for large-scale RLHF and GRPO training.
Scaling MoE reinforcement learning on Amazon EKS with EFA and DeepEP with 40% more throughput
Publication summary. The terms of AWS Machine Learning do not allow reproduction of the full article: read the complete text on the original website.
Source summary (English)
Read the full article
aws.amazon.com