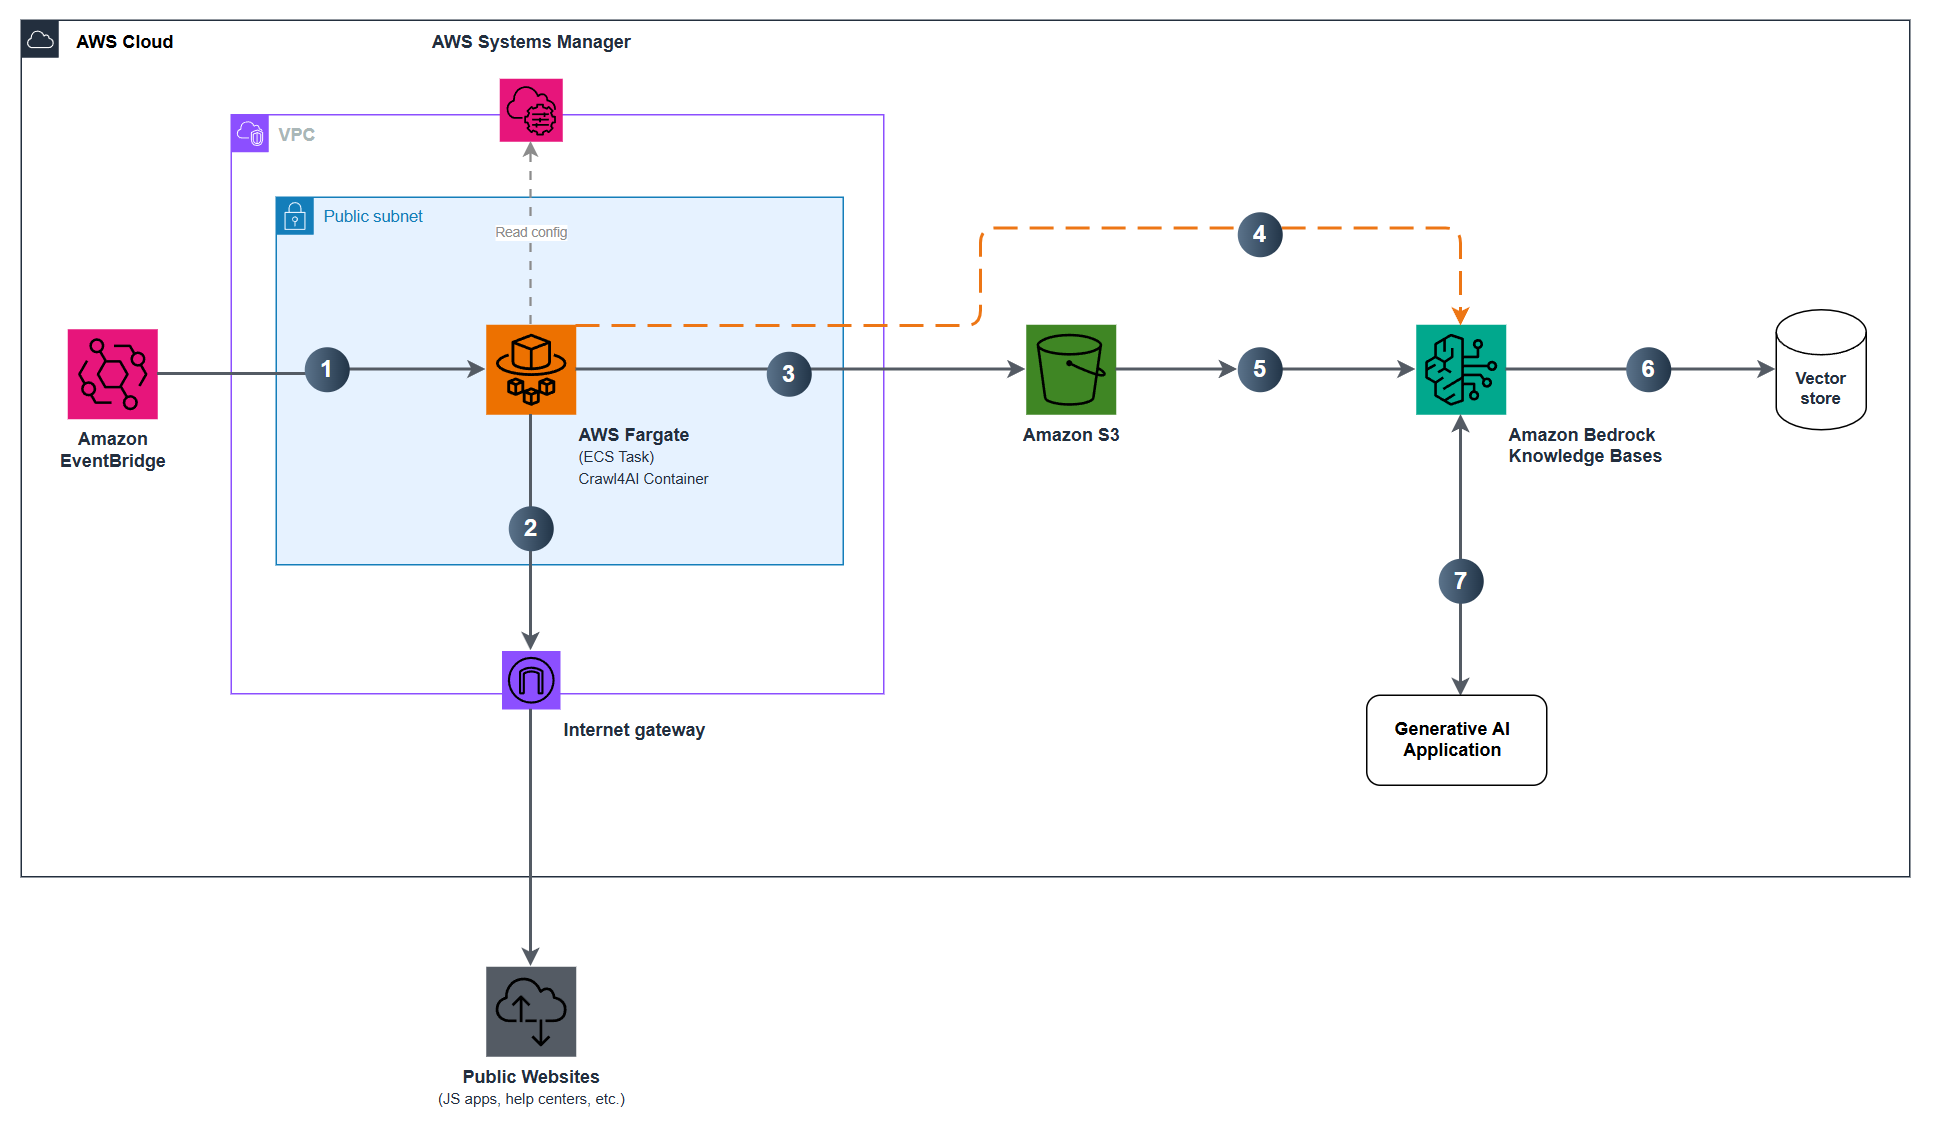
This post shows how to use Crawl4AI, an open source web crawler, as a content preparation layer for Amazon Bedrock Knowledge Bases, handling JavaScript rendering, selective extraction, and custom metadata enrichment before web content reaches an Amazon S3 data source.
Prepare web content for Amazon Bedrock Knowledge Bases with Crawl4AI
Publication summary. The terms of AWS Machine Learning do not allow reproduction of the full article: read the complete text on the original website.
Source summary (English)
Read the full article
aws.amazon.com