Learn how we fine-tuned GPT-OSS-20B for multilingual reasoning on Amazon SageMaker HyperPod, and how to decide between supervised fine-tuning (SFT) and reinforcement learning with GRPO. SFT took reasoning-language accuracy from 22% to 100%, and GRPO added measurable gains where headroom existed.
Fine-tuning GPT-OSS-20B for multilingual reasoning on Amazon SageMaker HyperPod
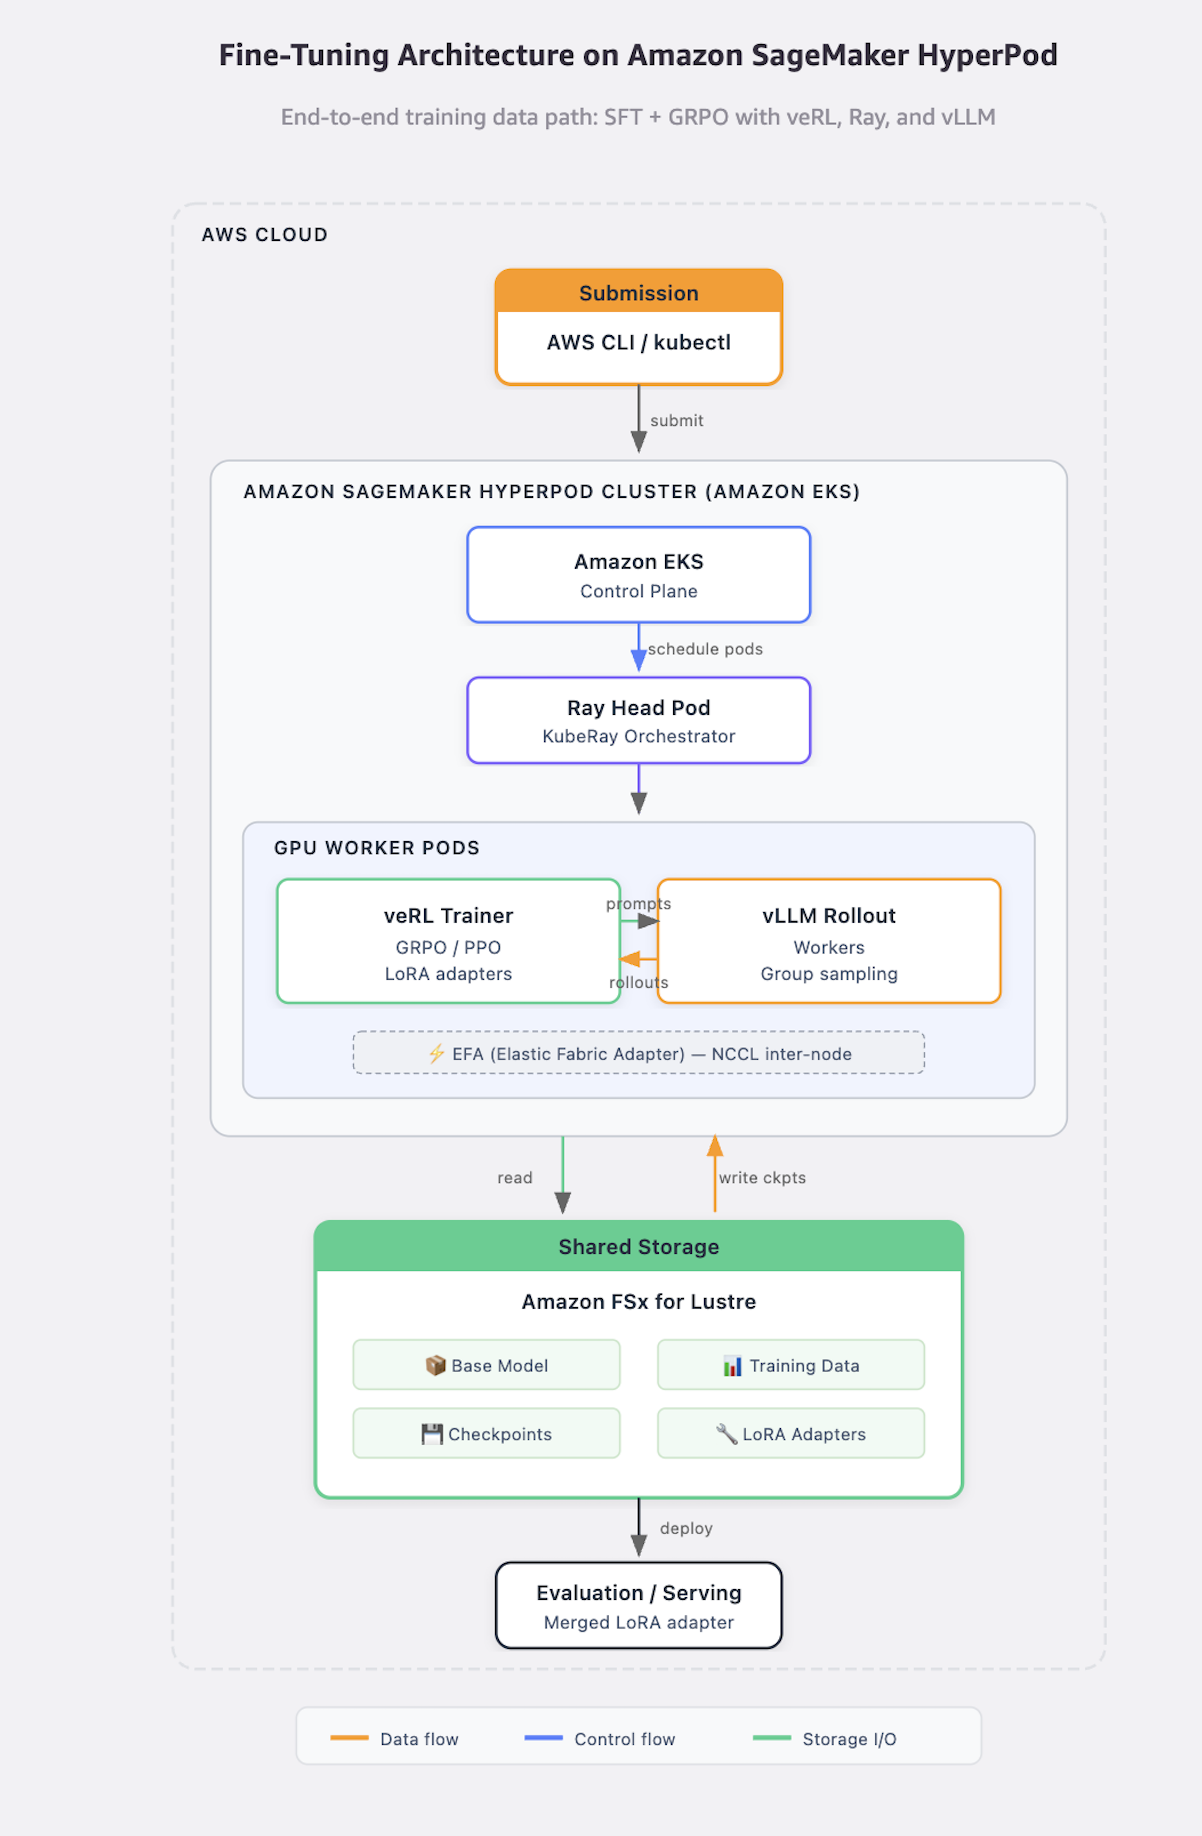
Publication summary. The terms of AWS Machine Learning do not allow reproduction of the full article: read the complete text on the original website.
Source summary (English)
Read the full article
aws.amazon.com